
Creative workflows
How to Make a Thanksgiving Dinner AI Video From Your Family's Photos
One tested way to put two adults at a Thanksgiving table from separate photos: the prompt, the 5-second clip, what differed, and what we did not test.
Video examples here were generated on Cicadas and keep their model, settings and date. Cicadas earns money when you generate with these models. How we test
- Test window:
- 2026-09-27 – 2026-11-12
- Clips recorded with these models:
- 190
- Models:
- MiniMax H3 Max
- Their provider cost:
- ≈$56.58
- Selection:
- every clip we keep is listed with its settings, cost and request ID; failed or discarded runs are listed in the test record.
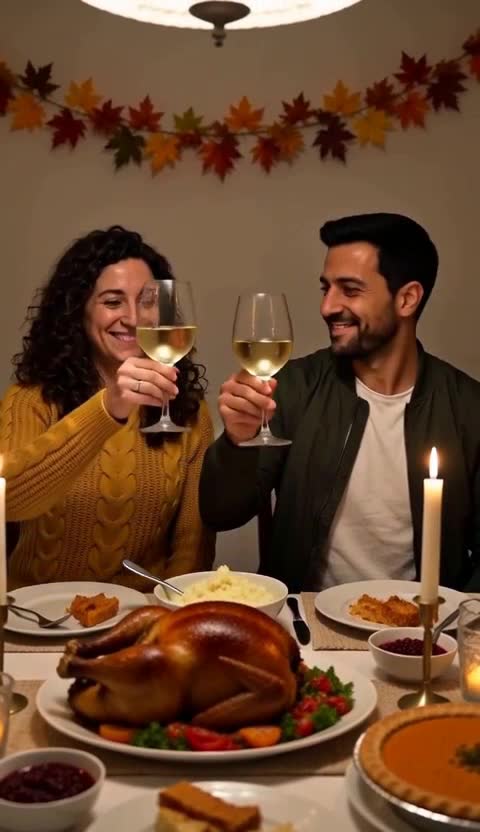
Short answer: to put real people at a Thanksgiving table, use a reference-to-video page, add one photo per adult, and call them "Image 1" and "Image 2" in the prompt. We ran that once with two sample photos on MiniMax H3 Max: 5 seconds, 480P, 9:16, with sound, USD 0.25 at the list price. The prompt, the clip and what differed are below. The Thanksgiving page itself works from text only and shows no people.
Cicadas is our site, so the tool links below point to our own pages. The two-person clip was generated on November 12, 2026 from the site's own sample photos of a woman and a man; the table clip was generated on October 13, 2026 from text. What we say a clip shows comes from frame sheets we looked at. Sound in the new clip was measured (mean −28.8 dB, max −7.2 dB), not listened to, so we quote what the prompt asked for and do not describe what you hear.
Two pages, two jobs
- AI Thanksgiving video takes no photos. It has three text scenes: a candle-lit table, a turkey in a pilgrim hat and blowing maple leaves. Nobody sits at that table.
- AI reference to video takes one to three photos and a prompt you write. This is the page for people.
The prompt we ran, word for word
Image 1 was the woman's photo and Image 2 the man's.
One continuous shot at a Thanksgiving dinner table at home in the evening. The woman from Image 1 and the man from Image 2 sit side by side behind the table, facing the camera. On the table: a roast turkey on a platter, mashed potatoes, cranberry sauce, a pumpkin pie and two lit candles; a garland of autumn leaves hangs on the wall behind them. They raise their glasses toward the camera, clink them together, smile and laugh, and the woman passes a bowl to the man. Keep both faces and hair exactly as in the photos. Handheld family-video feel, medium shot from across the table, warm light. Sound: glasses clinking, cutlery on plates, soft laughter. No text, no logos.
What came out: the two sit side by side behind a table with a roast turkey, mashed potatoes, a pie, cranberry sauce, candles and wine glasses, under a garland of autumn leaves. They raise their glasses, clink them and laugh. Her curly hair and mustard sweater and his beard and green jacket match the photos.
What differed from the prompt:
- The prompt has the woman pass a bowl to the man. In the clip her hand goes to a bowl of mashed potatoes and he ends up holding it; the pass is brief and partly hidden.
- The glasses hold white wine. The prompt named no drink.
- The prompt asked for two candles; the table has more.
Five seconds held one clear action, the toast. The second action was squeezed into the last second, so one action per clip is the safer brief.
What we did not test
One clip is one test. We did not record a single group photo, three people, or anyone under 18, and we promise none of them. Use photos of adults who agreed. Do not upload photos of children. The model does not lock an identity: it redraws each person, so a face can drift between the first and the last second.
The no-photo option
If nobody should appear, the text scene is enough:
More dinner scenes (not recorded by us)
These follow the same pattern. We have not run them, so we do not know how they come out. Swap the action sentence and keep the rest.
- Carving: Image 1 carves the turkey while Image 2 holds out a plate.
- Passing dishes: Image 1 hands a basket of bread rolls across the table to Image 2.
- Toast: both stand behind their chairs and raise their glasses to the camera.
- Pie: Image 1 sets a pumpkin pie on the table and Image 2 claps.
- Doorway welcome: Image 1 opens the front door and hugs Image 2, who holds a covered dish.
How to do it on Cicadas
- Choose one sharp, front-facing photo of each adult, with the face large and unobstructed.
- Open AI reference to video and add the photos in the order you will name them.
- Paste the prompt above, change the dishes or the room, and keep "Keep both faces and hair exactly as in the photos" and "No text, no logos".
- Read the quote, generate, then pause at the start, middle and end next to the photos.
- Add "Happy Thanksgiving" and the names in your phone's editor; the prompt asks for no writing.
Cost: MiniMax H3 Max on Cicadas is 63 credits for 5 seconds at 480P, about USD 0.62 on the first credit pack, quoted before you generate. Thanksgiving is on November 26, 2026, and our run came back from the provider in about 10 seconds, so there is time for a second try. For other seasonal pages see the AI holiday video generator and, for December, the Christmas card video. More on using your own photo is in how to put yourself in an AI video, and on wording in the MiniMax H3 prompt guide.
Questions
Can AI put my family at a Thanksgiving dinner table from photos?
Partly. With one photo per person on a reference-to-video page, the model draws those people into a new dinner scene. We recorded two adults from two separate photos; three people is the page's limit and we have not recorded it.
Can I upload one group photo of the whole family?
We have not tested that. Our clip used a separate photo for each person, named Image 1 and Image 2 in the prompt, and that is the setup we can describe. A group photo may work differently.
How many people can be in the clip?
The reference page accepts one to three photos, so three named people at most. We recorded two. More faces in a short clip leave the model less room for each one, so check every face.
Can I include my children in the video?
No. Use photos of adults who agreed to it. Do not upload photos of children. For a clip with no people at all, the Thanksgiving page makes a table, a turkey or autumn leaves from text.
Will the faces look exactly like the photos?
Not guaranteed. In our clip the curly hair, the beard and the clothes matched the two photos, but the model redraws people into a new scene and can change details. Pause the clip next to the photos before you send it.
Tools used in this guide
- AI Thanksgiving Video GeneratorAI Thanksgiving video: a candle-lit dinner table, a strutting turkey in a pilgrim hat or swirling autumn leaves, as a 5-second clip with sound. 63 credits.
- AI Reference to Video: Consistent CharactersAI Reference to Video: Consistent Characters. Make a 5–15 second clip with MiniMax H3 Max. Start at 63 credits; inspect the quote and download from My videos.
- AI Holiday Video GeneratorAI holiday video generator: choose Thanksgiving, Black Friday, Christmas, snow or New Year. Find the matching tool or make a short greeting from text.