
Model updates
MiniMax H3 Prompt Guide: Templates From 160 Recorded H3 Max Clips
How to write a MiniMax H3 prompt, from 160 H3 Max clips we recorded: the sentence order that held, copyable templates for text, photo and reference, and what the model ignored.
Video examples here were generated on Cicadas and keep their model, settings and date. Cicadas earns money when you generate with these models. How we test
- Test window:
- 2026-09-27 – 2026-10-30
- Clips recorded with these models:
- 160
- Models:
- MiniMax H3 Max
- Their provider cost:
- ≈$46.08
- Selection:
- every clip we keep is listed with its settings, cost and request ID; failed or discarded runs are listed in the test record.
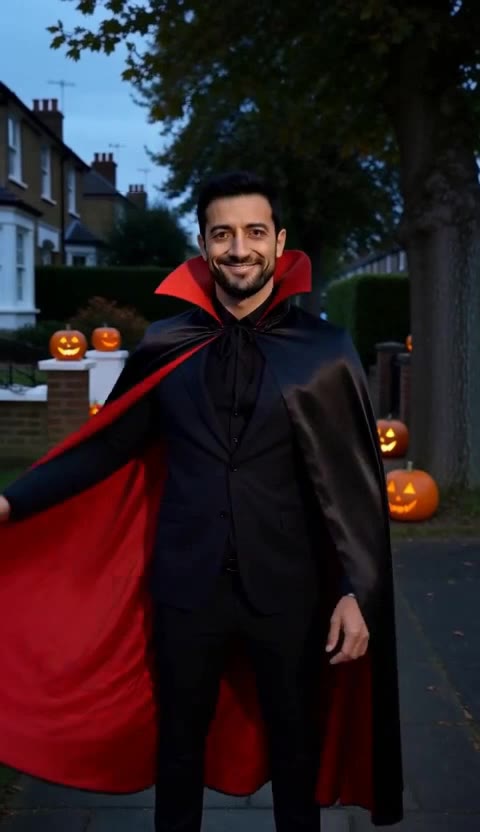
Short answer: a MiniMax H3 prompt works best as a short scene description in a fixed order: what kind of footage and where, who is in it, one action, the camera, the sound, and what must stay out of the picture. We recorded 160 clips on MiniMax H3 Max for the pages on Cicadas, and that order is the one almost all of them share. The model followed the place, the people and the camera in most clips. It followed the sound least, it loosened any list of moves, and it sometimes drew a thing we only mentioned.
We make Cicadas, an AI video site that runs MiniMax H3 Max and other models through fal.ai. This guide reads our own records: 160 H3 Max clips recorded between 27 September and 30 October 2026, each sent once with the exact prompt shown on its page, watched, and described in a note. 55 are text to video, 35 start from a photo as the first frame, and 70 use one to three photos as a reference. They sit on 61 pages, and 83 of them carry a note about something that came out differently from the prompt. Every clip below is named so you can watch it on its page.
1. The order that held
Two prompts that came back as written show the pattern. From the birthday page, birthday-candles:
A kitchen table in warm evening light, vertical. The adult from Image 1 sits in front of a small birthday cake with lit candles, smiles, takes a breath and blows the candles out, then looks up at the camera and laughs. Keep the face, hair and clothes as in the photo. The camera stays still, one continuous shot, no cuts. Sound: a soft puff of breath and quiet room tone, no music, no singing. No text, no numbers on the cake.
And from the Halloween costume page, costume-walk, which opens with the kind of footage before the place: "Vertical phone footage on a leafy suburban street at dusk on Halloween night, one continuous shot."
The parts, in order, and how often each appears across the 160 prompts:
- Footage and place: "Vertical phone footage in a warm kitchen at night". 119 of the prompts say vertical.
- Who: "The person from Image 1", or a described subject when there is no photo. All 70 reference prompts name "Image 1".
- One action: one chain of verbs with a clear end.
- Camera: "The camera stays still", or one named move. 138 of the prompts ask for one continuous shot.
- Sound: one or two sounds that belong to the place. 128 of the prompts have a "Sound:" sentence.
- Exclusions: "No text, no logos, no other people". 155 of the prompts say no text.
The prompts ran from 29 to 143 words, with a median of 79. Clips did not get better with more words; they got better with fewer actions.
2. Templates you can copy
Each template below is a shortened version of the prompt of a clip that came back as asked; the full prompt is on that clip's page. Replace the words in the scene, keep the order.
Text to video (from christmas-reindeer on the Christmas video page, minus its bells; see section 3):
A snowy forest clearing at blue hour with warm lights strung between two pines, vertical. A reindeer walks up to the camera, sniffs the lens and shakes the snow from its antlers. The camera stays still at its eye level, one continuous shot, no cuts. Sound: snow crunching, no music, no voices. No people, no text.
Photo as the first frame (from bouncy-hair-tilt on the bouncy hair page). Describe a small motion of what is already in the picture and tell the model to keep the rest:
The woman in the photo makes one small, relaxed head tilt to the left and returns to center. Her hair lifts slightly and settles. Keep her face, hair and the background exactly as in the photo. Fixed camera, one continuous shot, no text.
One photo as a reference (from costume-walk). The photo tells the model who; the sentence tells it where:
Vertical phone footage on a leafy street at dusk, one continuous shot. The person from Image 1 walks toward the camera, stops and grins. Keep the face, hair and build as in the photo. Sound: footsteps and a light wind, no music, no voices. No other people, no text, no logos.
Two photos (from couple-beach on the couple page). Give each photo its own role in the same sentence:
Vertical phone footage on a quiet beach at golden hour, one continuous shot. The person from Image 1 and the person from Image 2 walk along the waterline holding hands, then stop and hug. Keep both faces, hair and builds as in the photos. Natural sound only: waves and soft laughter, no music. No other people, no text.
A spoken line (from talking-pet-h3 on the talking pet page). Only the words go inside the quotation marks:
The pet in the photo looks into the camera, tilts its head and says in a warm, friendly voice: "Good morning! Is it breakfast time yet?" The camera stays still, one continuous shot. No music. No text.
In that clip the mouth opened on some of the words, not on every one, so keep spoken lines short. The talking photo page explains why a note like "(laughs)" inside the quotes is read out as words.
3. Sound is the line it follows least
Of the 83 notes, 33 are about sound. Three patterns repeat.
An action that makes a voice beats "no vocals". In raindance-pier on the rain dance page the prompt asks for a close-up of someone "singing softly" and also for no vocals; the model added a soft sung voice. Both clips on the hotel lobby page, hotel-lobby-duet and hotel-lobby-cat, ask for rapping and no vocals, and both came back with a voice in made-up words. On the Thanksgiving page, thanksgiving-turkey asks the turkey to gobble with no voices, and a squeaky voice says "Gobble, gobble!". If the picture needs a mouth moving, decide whether you want the voice, and write that.
Music where none was asked. hug-park on the hug page says no music and has guitar. minimax-coastal-drive on the MiniMax H3 page has no sound sentence at all, and the model chose soft piano. Leaving the sound out does not give you silence; H3 Max returns sound with every clip.
Small named sounds go missing. Twelve of our prompts mention bells, and the notes on four say the bells were not heard: santa-door-h3 and santa-tree-h3 on the Santa page, christmas-reindeer, and elf-dance on the elf page, where the listeners heard tapping footsteps instead. Name the one or two sounds that would be loudest in the real place.
4. Camera and timing
79 of the prompts ask for a still or locked camera, and the notes on two say the view moved anyway: in birthday-surprise it moves in through the doorway, and in pet-human-cat on the pet to human page it jumps closer as the change starts. In two more the camera held but the subject came to it: in santa-name-h3, a first-frame clip, Santa walks right up to the lens and hides most of the room, and in rumpel-hall on the Rumpelstiltskin page he ends so close that his sneakers leave the frame. If the whole figure matters, say where it stops.
Timing is looser than the words. age-portrait on the age progression page asks for a slow change "over the clip", and most of it happens in about one second in the middle. In younger-self-bench-hug on the hug my younger self page the hug comes only in the last second or so. A 10-second clip with three cuts, gas-dance-night-solo on the gas station dance page, gives each cut about three seconds, so the dance in it is a few steps.
142 of the 160 clips are 5 seconds long. Plan one change per five seconds, and say where it ends: "by the end they look about eighty" gave a clear end point even when the middle was fast.
5. Lists of moves come back loose
dance-studio on the AI dance page lists a bounce, a body roll, a cross-step, an arm sweep, a spin and a pose; the clip has a bounce, arm sweeps and a turn, in its own order. In couple-dance neither person rests a head on the other's shoulder, though the prompt asks for it. diwali-sparkler on the Diwali page asks for a slow circle of sparks, and the sparkler stays almost still. One clear action with a start and an end came back closer than any list.
6. What it draws that you did not ask for
Writing no text helps but does not guarantee it: minimax-city-rain has shop signs with unreadable lettering, and gas-dance-dusk-trio has made-up lettering on the pumps, though both prompts say no text.
Naming a thing can bring it into the picture. halloween-skeleton on the Halloween video page asks the skeleton to tip "an invisible hat", and the model drew a real top hat. In ice-volcano-drop on the popcorn volcano page a hand tips a blue bucket, and a second blue bucket appears on the cabin floor. muscle-gym-flex on the muscle page has a small round badge on the trousers that no line mentions. Leave out props you do not want on screen, even as a joke.
7. Labels, brackets and the prompt box
The generator box on Cicadas asks for one or two plain sentences covering what we see, what moves, the light and the mood, with no labels and no brackets. Our recorded prompts are longer because each carries a whole scene, but they keep the same habit: none of the 160 uses square brackets. The one label they do use is a short "Sound:" sentence, written as a sentence, and the multi-shot prompts name their shots in words ("Shot 1: ..."). If you write your own prompt, a plain description reads safer than a checklist: on the talking pages anything inside the quotation marks is spoken, and a stage note can turn into words.
8. Length, resolution and price
- 5 seconds: 63 credits at 480P, 100 credits at 768P.
- 10 seconds: 125 credits at 480P, 200 credits at 768P.
- 15 seconds: 188 credits at 480P, 300 credits at 768P.
The price is the same for text, a first-frame photo or a reference photo. 63 credits is about $0.62 on the $9.90 first pack of 1,000 credits. 152 of our 160 clips were made at 480P, which is enough to check a prompt; move to 768P once the prompt does what you want. The quote shows on the page before you generate, and failed clips refund their credits.
For the endpoint details and the settings fal exposes, read our MiniMax H3 Max guide. To try a prompt, use the MiniMax H3 page.
How we checked
The 160 clips are every MiniMax H3 Max clip recorded on Cicadas through fal.ai between 27 September and 30 October 2026 and published on a page, counted from the site's own records on 1 November 2026. Each was sent once with the prompt shown on its page; where a page shows a second take, the page says so. Photos of people are AI-made sample photos of fictional adults. Sound notes come from listening to each clip, with an automated check on some; where two listeners heard different things, the note says so. The counts of prompt parts were made by searching the 160 prompts for the phrases quoted in this guide. See how we test.